Query-driven Knowledge Integration for a Decentralized Web

Ruben Taelman

UHasselt 2026, 2 October 2026

Query-driven Knowledge Integration

for a Decentralized Web

Ghent University – imec – IDLab, Belgium

Data is highly decentralized

Decentralized data integration is challenging for application developers

Query engines abstract access to decentralized data

Hide the complexities of reading and writing for app developers
Application ↔ Gear ↔ Globe

Image credit

Focus on Knowledge Graphs

SPARQL processing over centralized data

Centralization not always possible

How to query over decentralized data?

Approaches for querying over decentralized data

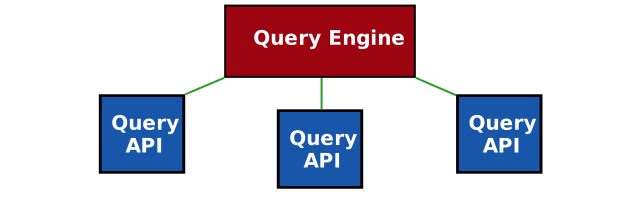
Client distributes query over query APIs

Federation over SPARQL endpoints

SELECT ?drug ?title WHERE {
  ?drug db:drugCategory dbc:micronutrient.
  ?drug db:casRegistryNumber ?id.
  ?keggDrug rdf:type kegg :Drug.
  ?keggDrug bio2rdf:xRef ?id.
  ?keggDrug purl:title ?title.
}


SELECT ?drug ?title WHERE {
  SERVICE <http://example.com/drb> {
    ?drug db:drugCategory dbc:micronutrient.
    ?drug db:casRegistryNumber ?id.
  }
  SERVICE <http://example.com/kegg> {
    ?keggDrug rdf:type kegg :Drug.
    ?keggDrug bio2rdf:xRef ?id.
    ?keggDrug purl:title ?title.
  }
}

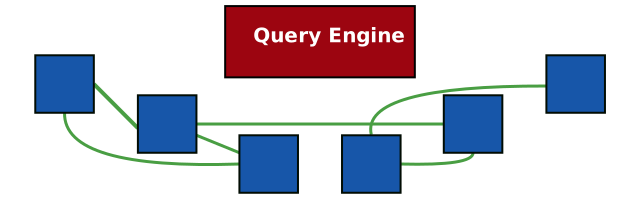
Federation over heterogeneous sources

Limitations of federated querying

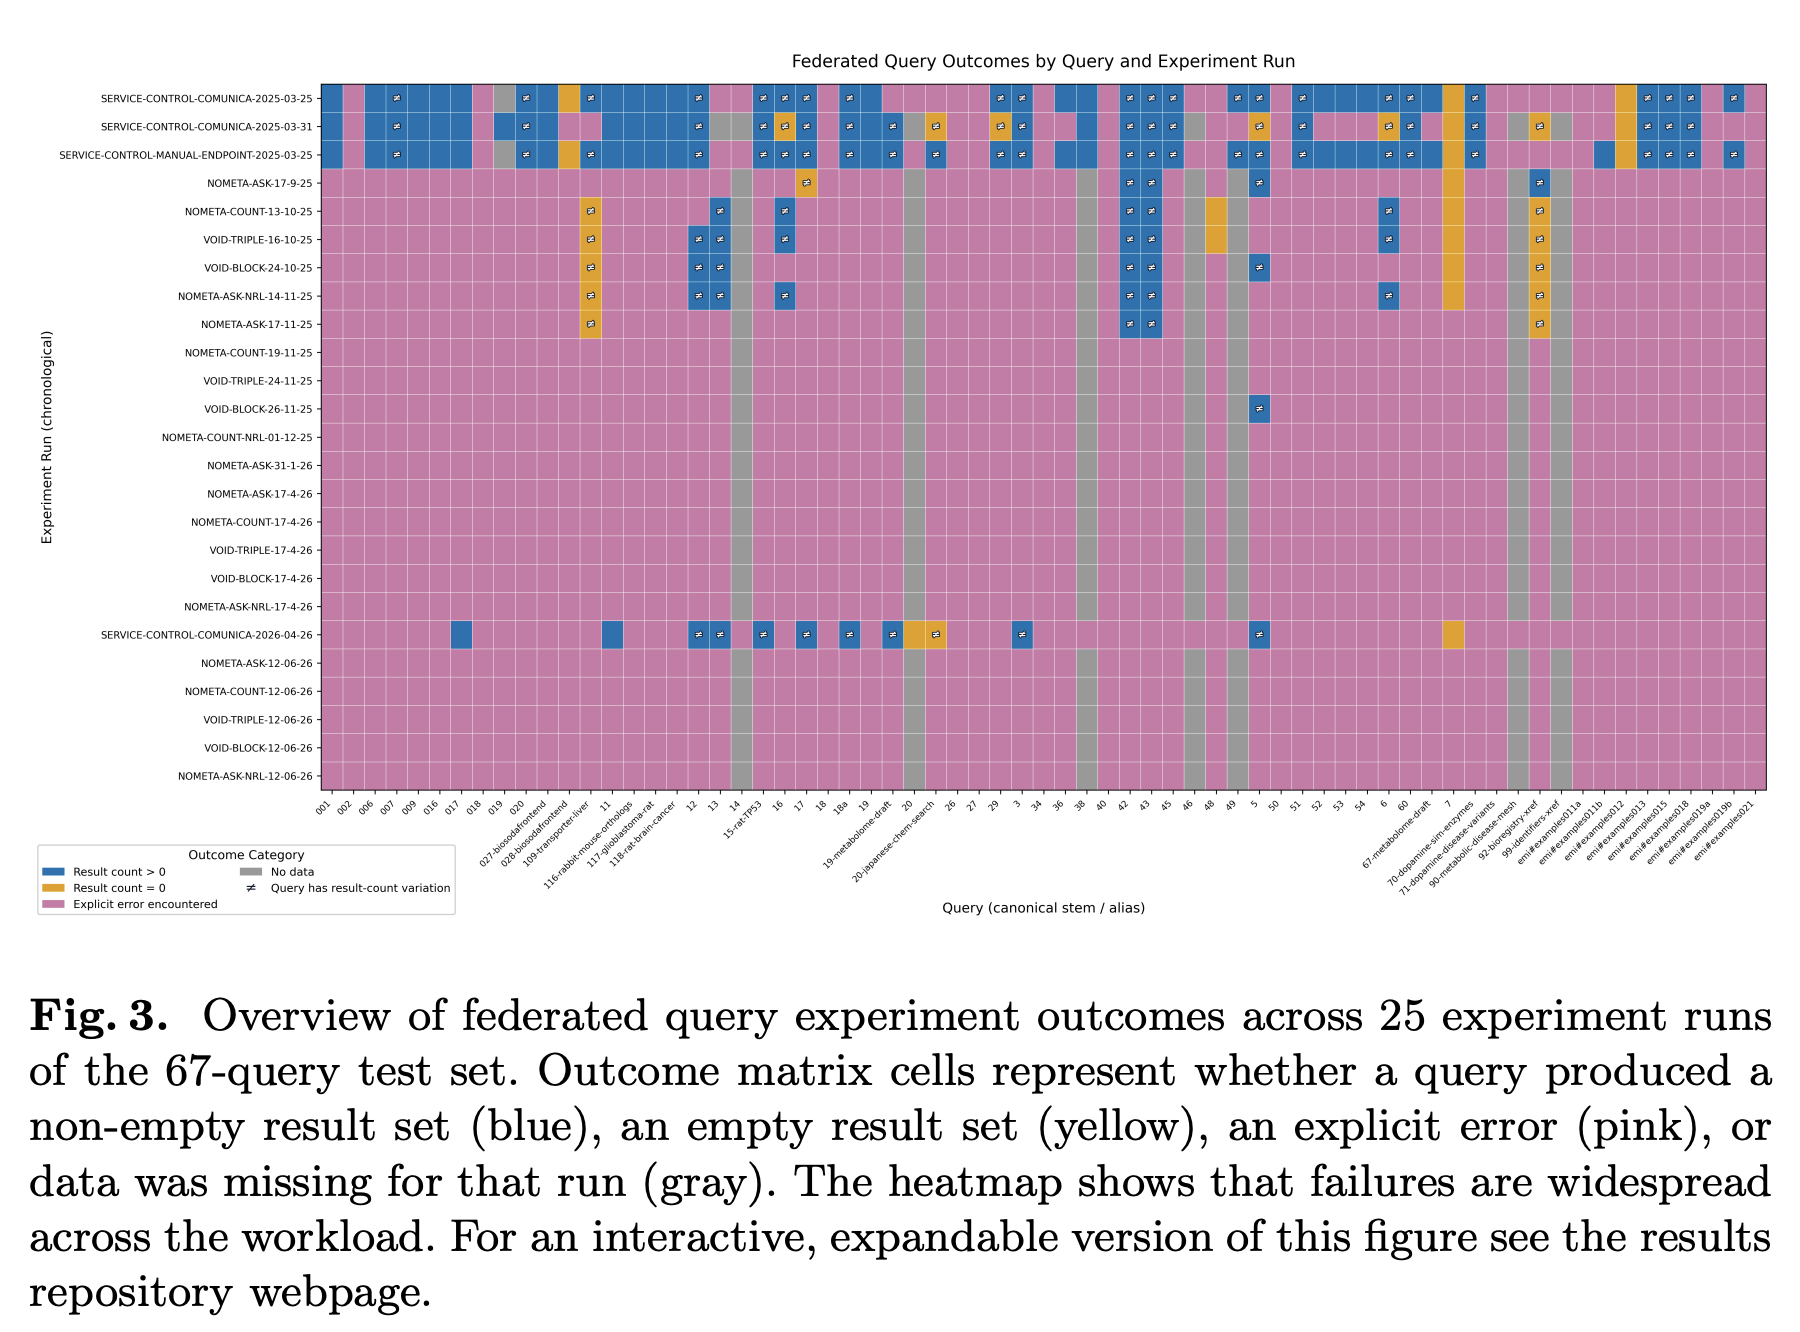
Federated querying over public endpoints in practise does not work due to restrictions

Real federation findings

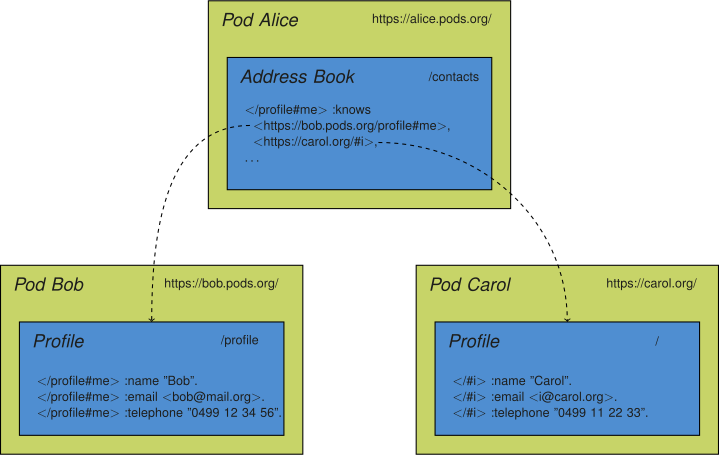
Example: decentralized address book

Example: Find Alice's contact names

SELECT ?name WHERE {
    <https://alice.pods.org/profile#me>
        foaf:knows ?person.
    ?person foaf:name ?name.
}

Query process:

  1. Start from Alice's address book
  2. Follow links to profiles of Bob and Carol
  3. Query over union of all profiles
  4. Find query results: [ { "name": "Bob" }, { "name": "Carol" } ]
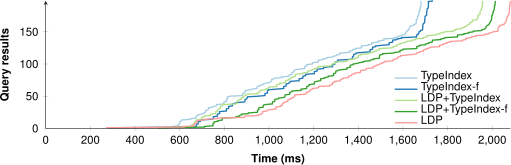
Link Traversal: too slow for querying over Linked Open Data

Link Traversal becomes feasible with structural assumptions

Solid pods follow structural properties

If pods expose more information, complex querying can become faster

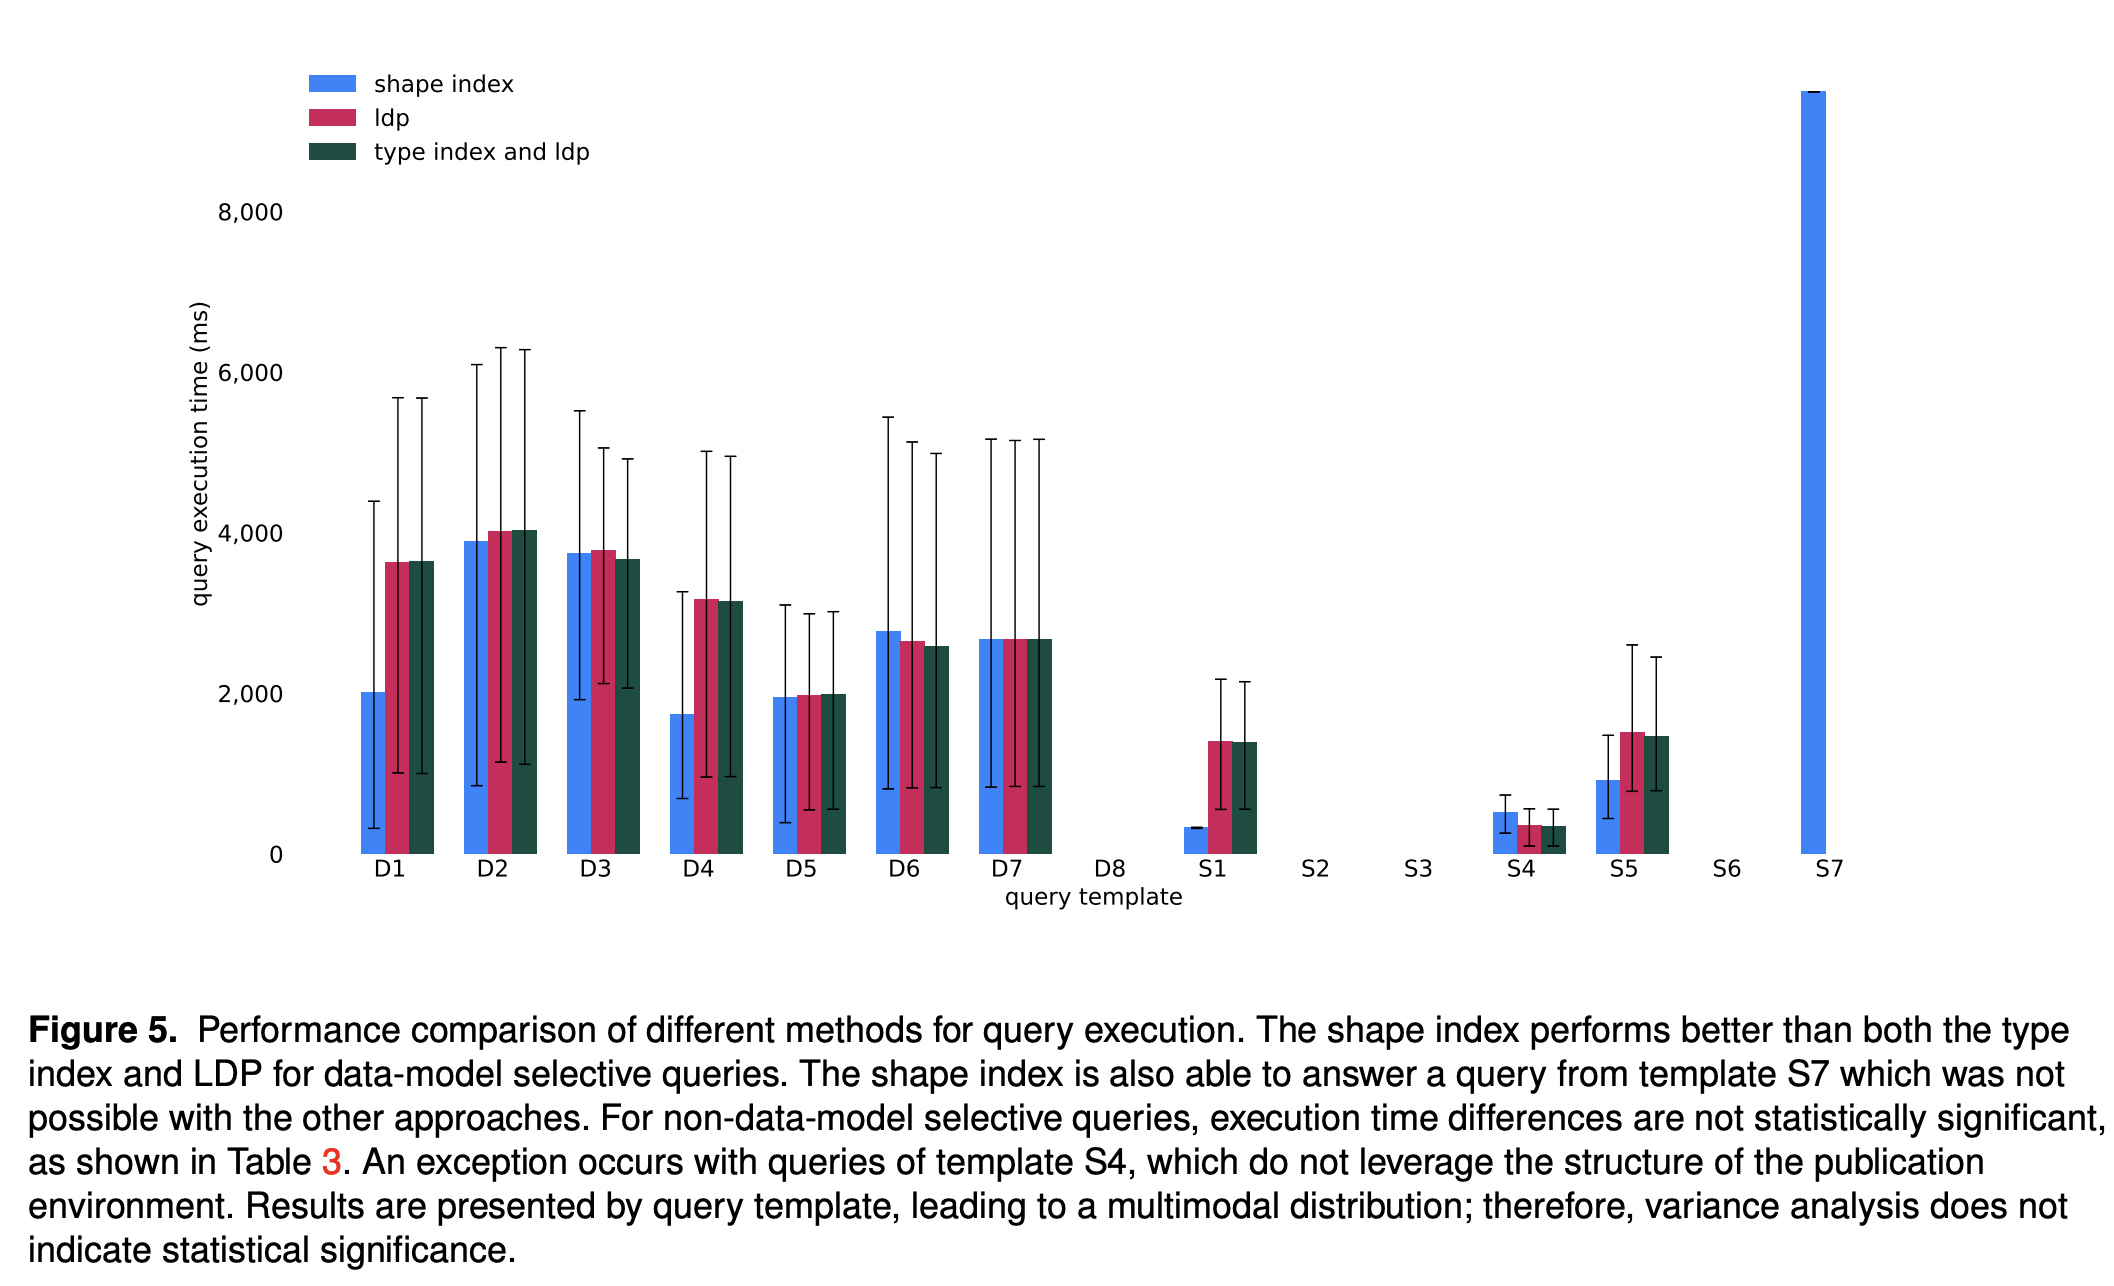
Pods exposing shape information allows query engines to skip many links

Shape index

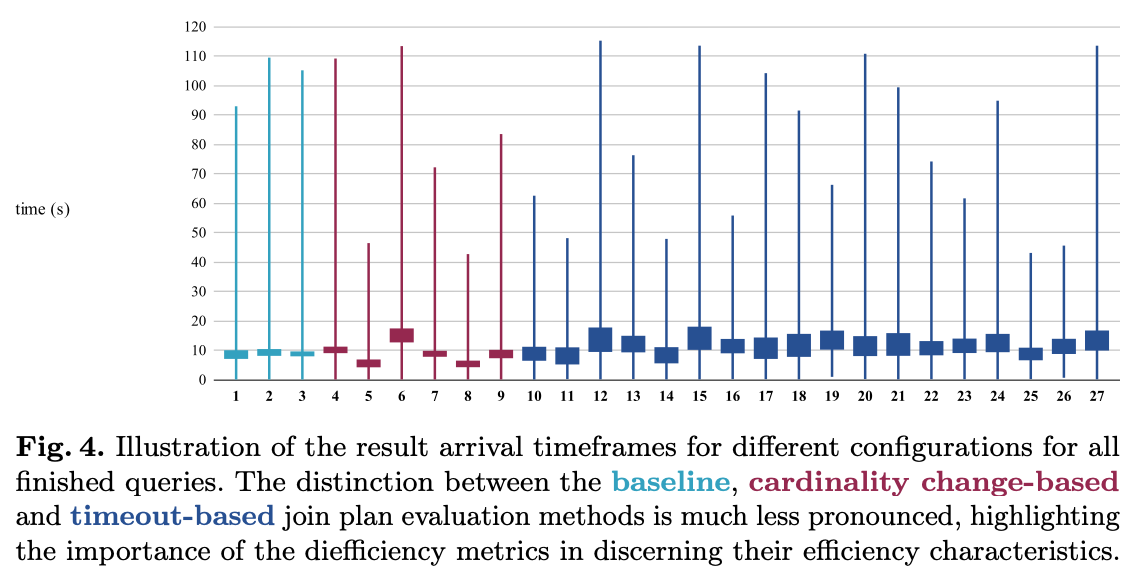
Pods exposing cardinality information allows engines to make better query plans

Query plan times

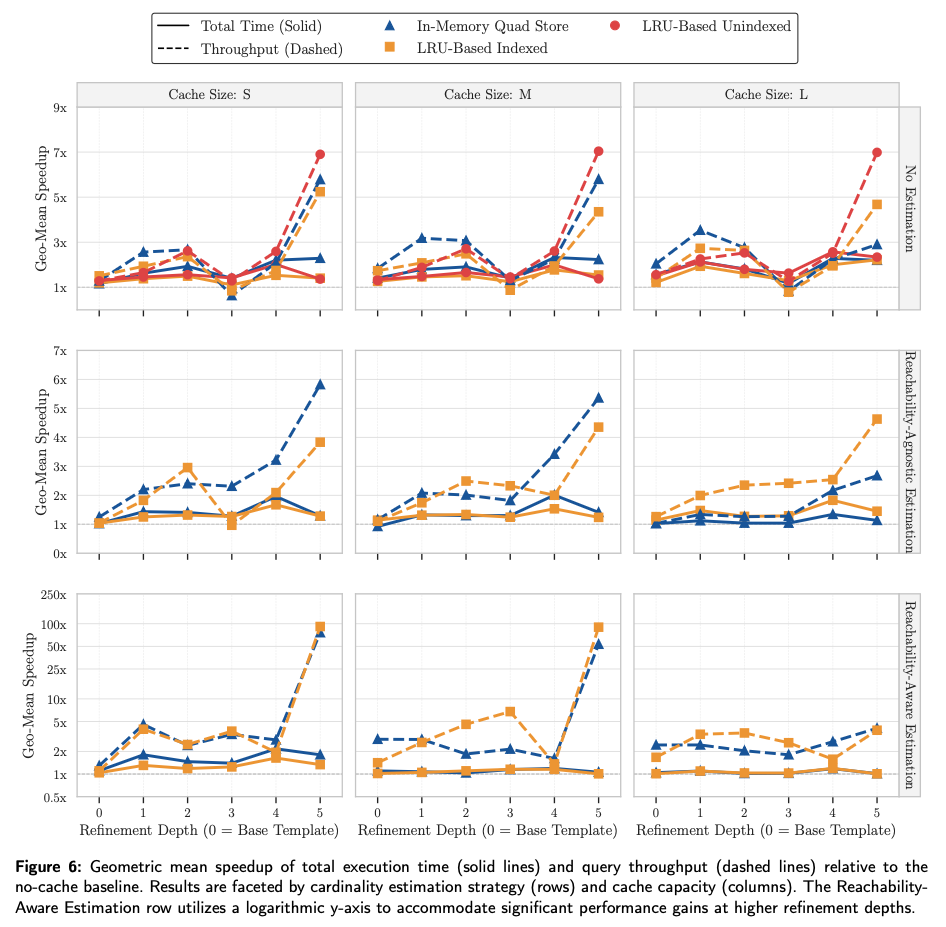
Client-side caching across improves performance within user sessions

SolidSessionBench

Conclusion: Query engines are a good match for integrating decentralized data

Personal Retrieval and Integration team KNoWS / IDLab / UGent

We develop the Comunica framework

https://comunica.dev/

The future of RDF and SPARQL

https://www.w3.org/TR/sparql12-query/